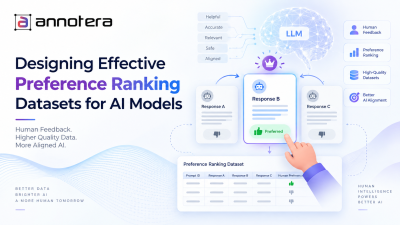
As AI models become more capable, improving performance is no longer only about increasing model size or adding more training data. Modern language models need to learn which outputs are more useful, accurate, relevant, safe, and aligned with user intent. This is where preference ranking datasets play a critical role.
Preference datasets capture human judgments by comparing multiple model-generated responses and identifying which response better satisfies a defined set of criteria. These comparisons can then support reward modeling, preference optimization, and other post-training approaches. Anthropic’s publicly released human-preference dataset, for example, uses paired “chosen” and “rejected” responses for helpfulness and harmlessness training.
However, collecting preference data is not simply a matter of asking annotators to choose Response A or Response B. Poorly designed comparisons can introduce inconsistency, hidden biases, and misleading training signals. Effective preference ranking therefore requires thoughtful task design, clear evaluation criteria, qualified annotators, and rigorous quality assurance.
What Is a Preference Ranking Dataset?
A preference ranking dataset contains prompts or tasks alongside multiple candidate responses that have been evaluated by human annotators.
A simple example might look like:
Prompt: Explain how photosynthesis works.
Response A: Technically accurate but overly complex.
Response B: Accurate, concise, and easier to understand.
Human preference: Response B.
In a pairwise setup, the dataset may record the preferred and rejected responses. More complex workflows can ask annotators to rank three or more outputs or indicate the strength of their preference.
Preference data provides a comparative signal rather than relying solely on absolute scores. Comparative judgments can be easier for people to make consistently because annotators are deciding which of two outputs better meets a defined objective. Preference data is consequently an important component of RLHF and preference-based model training.
1. Start With a Clearly Defined Objective
The first step in designing a preference dataset is defining what the model should learn.
“Choose the best response” is usually too vague. Instead, annotation guidelines should explain what makes one response preferable.
Depending on the application, criteria could include:
Instruction adherence
Factual accuracy
Relevance
Completeness
Clarity
Helpfulness
Safety
Tone
Context awareness
Appropriate uncertainty
For example, a customer-service model may prioritize resolution accuracy and professionalism, while a coding assistant may require functional correctness, security, and adherence to technical requirements.
The evaluation framework should therefore reflect the intended behavior of the model rather than generic notions of quality.
2. Design Meaningful Comparisons
The quality of a preference dataset depends heavily on the quality of the comparisons presented to annotators.
Candidate responses should be sufficiently different to reveal meaningful behavioral distinctions. If two responses are almost identical, the resulting preference may provide little useful information. Conversely, if one response is obviously nonsensical, the comparison may be too easy to contribute much learning value.
A balanced dataset should include:
Clear wins and losses
Close comparisons
Edge cases
Ambiguous examples
Different levels of response quality
Challenging prompts
Realistic user scenarios
This gives models a broader representation of the behaviors they need to distinguish.
3. Give Annotators the Full Context
A response should rarely be evaluated independently from the task that generated it.
Annotators may need access to:
System instructions
User prompts
Conversation history
Reference documents
Tool outputs
Expected response formats
Domain-specific requirements
For example, an answer that appears correct in isolation may violate an earlier instruction in a multi-turn conversation. Similarly, a response may appear detailed and useful but contradict information contained in an approved reference document.
Context-aware evaluation helps ensure that preference labels represent actual task performance rather than surface-level writing quality.
4. Build a Structured Annotation Rubric
A detailed rubric helps different annotators apply the same standards.
Instead of simply asking:
Which response is better?
an annotation interface could ask:
Primary preference: A / B / Tie
Instruction adherence: A / B / Equal
Factual accuracy: A / B / Equal
Relevance: A / B / Equal
Safety: A / B / Equal
Confidence: High / Medium / Low
A structured approach provides richer information for dataset analysis and quality control. Annotera's existing guidance on RLHF annotation similarly emphasizes clear criteria, multi-axis evaluation, annotator calibration, and quality assurance.
The rubric should remain practical, however. Excessive evaluation dimensions can increase annotation time and create confusion.
5. Select and Train the Right Annotators
Not every preference task requires the same level of expertise.
General-purpose conversational data may be evaluated by trained generalist annotators. Specialized datasets involving programming, scientific research, finance, law, or technical engineering may require domain-qualified reviewers.
Annotator training should cover:
The purpose of the project
Evaluation criteria
Common error patterns
Examples of acceptable and unacceptable outputs
Difficult edge cases
Tie-breaking procedures
Escalation rules
Calibration exercises are particularly useful. Annotators can independently evaluate a set of examples and then compare their decisions against established reference judgments.
6. Measure Agreement and Investigate Disagreements
Preference datasets should not assume that every human judgment is equally reliable.
Multiple annotators can evaluate selected samples to measure consistency. When disagreements occur, the objective should not simply be to eliminate disagreement. Instead, teams should investigate why disagreement happened.
Common causes include:
Ambiguous guidelines
Missing context
Genuine trade-offs
Domain complexity
Annotator misunderstanding
Poorly designed prompts
Disagreement analysis can reveal weaknesses in the rubric and help teams improve future annotation rounds.
7. Build Quality Assurance Into the Pipeline
Quality control should operate throughout the data lifecycle rather than only at the end.
Effective QA may include:
Gold-standard tasks: Known examples used to assess annotator consistency.
Consensus review: Multiple annotators evaluate high-impact or difficult examples.
Random audits: Completed annotations are periodically reviewed.
Outlier detection: Unusual annotation patterns can be investigated.
Adjudication: Experienced reviewers resolve persistent disagreements.
Feedback loops: Findings from quality audits are incorporated into updated instructions and training.
This approach prevents low-quality judgments from becoming a large-scale training signal.
8. Avoid Hidden Biases in Preference Data
Human preferences can reflect unintended biases. Annotators may favor longer responses, confident language, particular writing styles, or certain formatting even when those characteristics do not improve actual task performance.
For this reason, preference datasets should be monitored for patterns such as:
Length bias
Stylistic bias
Excessive verbosity
Overconfidence
Sycophantic responses
Unnecessary refusals
Demographic or cultural bias
The objective is to ensure that the model learns the desired behavior, not superficial characteristics that happen to correlate with preferred responses.
9. Keep Dataset Structure Consistent
A well-designed dataset should maintain standardized metadata.
Useful fields can include:
Prompt ID
Conversation context
Candidate responses
Preferred response
Rejected response
Evaluation dimensions
Annotator ID
Confidence
Review status
Domain/category
Model version
Timestamp
Maintaining this structure makes datasets easier to audit, filter, version, and reuse during subsequent training cycles.
How Annotera Supports Preference Ranking Data
Creating high-quality preference datasets requires more than collecting large numbers of comparisons. It requires a workflow designed around the model's intended behavior.
Annotera's LLM & GenAI annotation services can support preference ranking workflows involving response comparison, instruction-following evaluation, factuality assessment, safety review, conversational quality, and domain-specific judgments.
Through structured guidelines, trained annotators, calibration, multi-level QA, and systematic review, organizations can develop reliable human feedback datasets aligned with their post-training objectives.
These workflows can form an important part of RLHF & fine-tuning data, helping AI teams translate human judgments into structured signals for improving model behavior.
Building Better AI Starts With Better Preference Data
Preference ranking datasets are a foundational component of modern AI post-training. Their value depends not simply on dataset size, but on the quality and relevance of the judgments they contain.
Effective datasets combine clear objectives, meaningful comparisons, contextual evaluation, trained annotators, structured rubrics, quality assurance, and ongoing analysis. They should also evolve as models improve and new failure modes emerge.
For AI teams, the goal is ultimately straightforward: create preference signals that accurately represent the behaviors the model is expected to learn. With carefully designed RLHF & fine-tuning data, preference annotation can become a practical bridge between human expectations and model behavior.
Looking to build reliable preference datasets for your AI models? Partner with Annotera to develop scalable, quality-focused human feedback workflows through our LLM & GenAI annotation services.